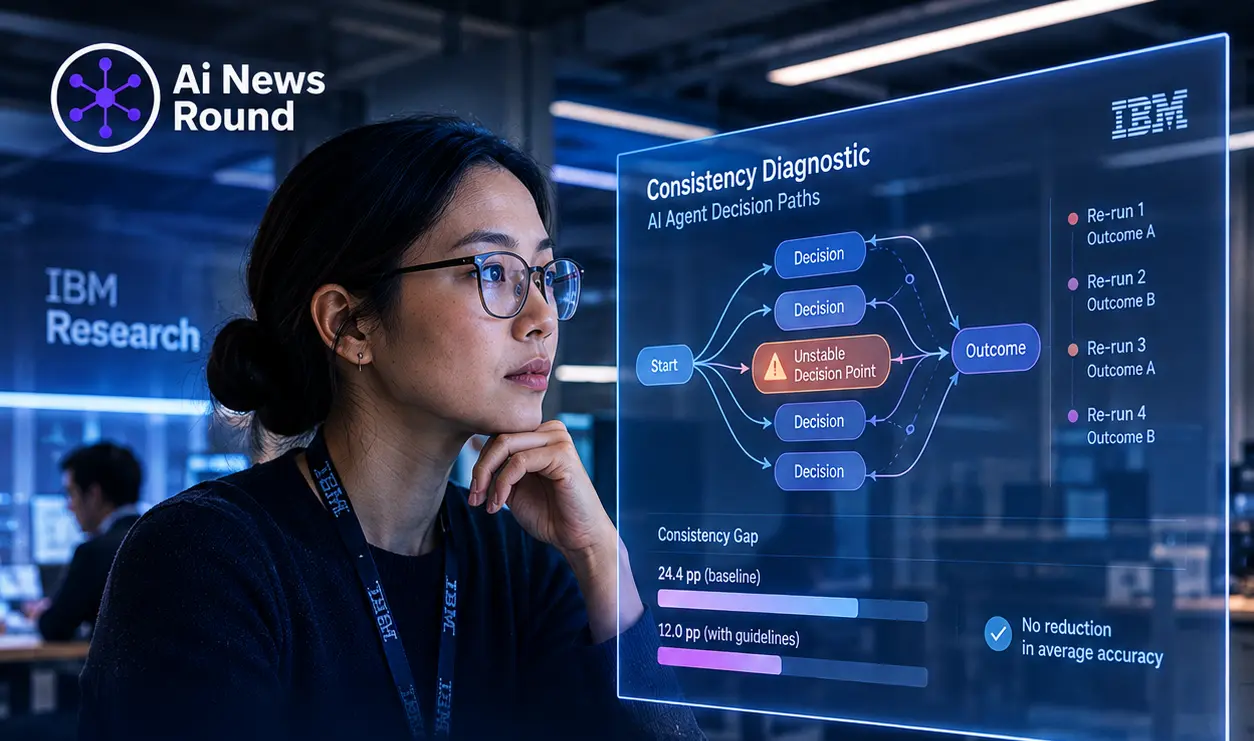
IBM Research has addressed the unreliability issue in artificial intelligence agents that pass tests on initial attempts but fail upon repetition. By evaluating decision uncertainty step by step, their new method identifies potential failure points and generates targeted guidelines to ensure repeatable execution.
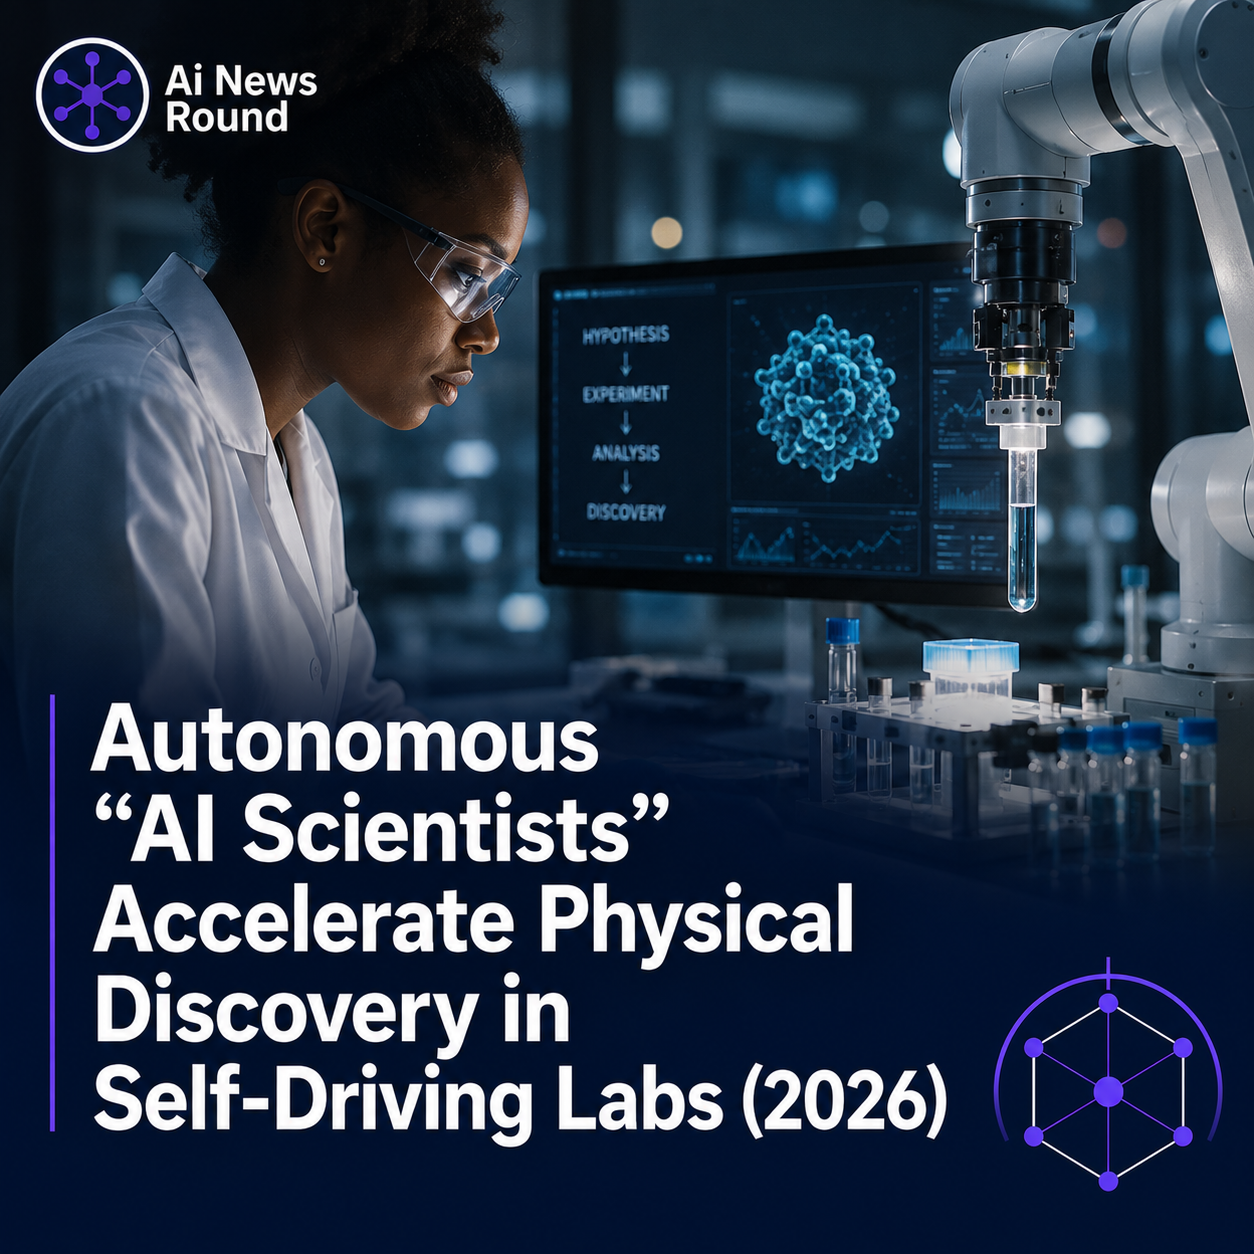
Across global research institutions and self-driving laboratories, Autonomous AI Scientists are taking over the experimental pipeline—independently formulating hypotheses, executing lab tests via connected hardware, and self-correcting results up to ten times faster than humanly possible.
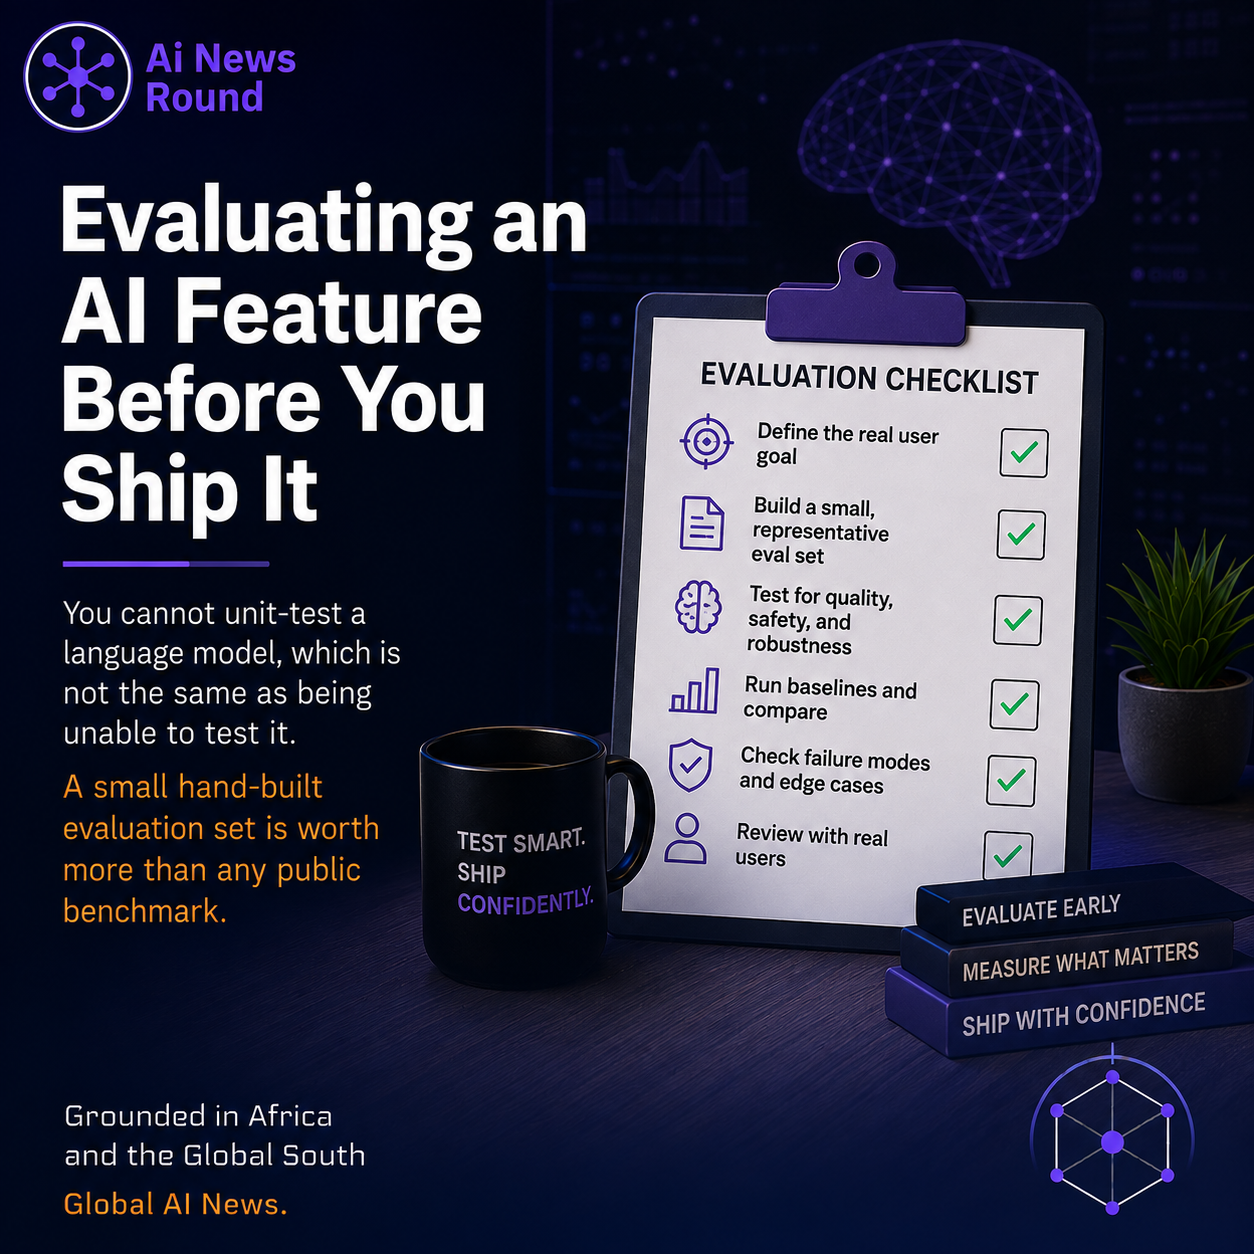
You cannot unit-test a language model, which is not the same as being unable to test it. A small hand-built evaluation set is worth more than any public benchmark.