Enhanced Performance Across Enterprise Workflows
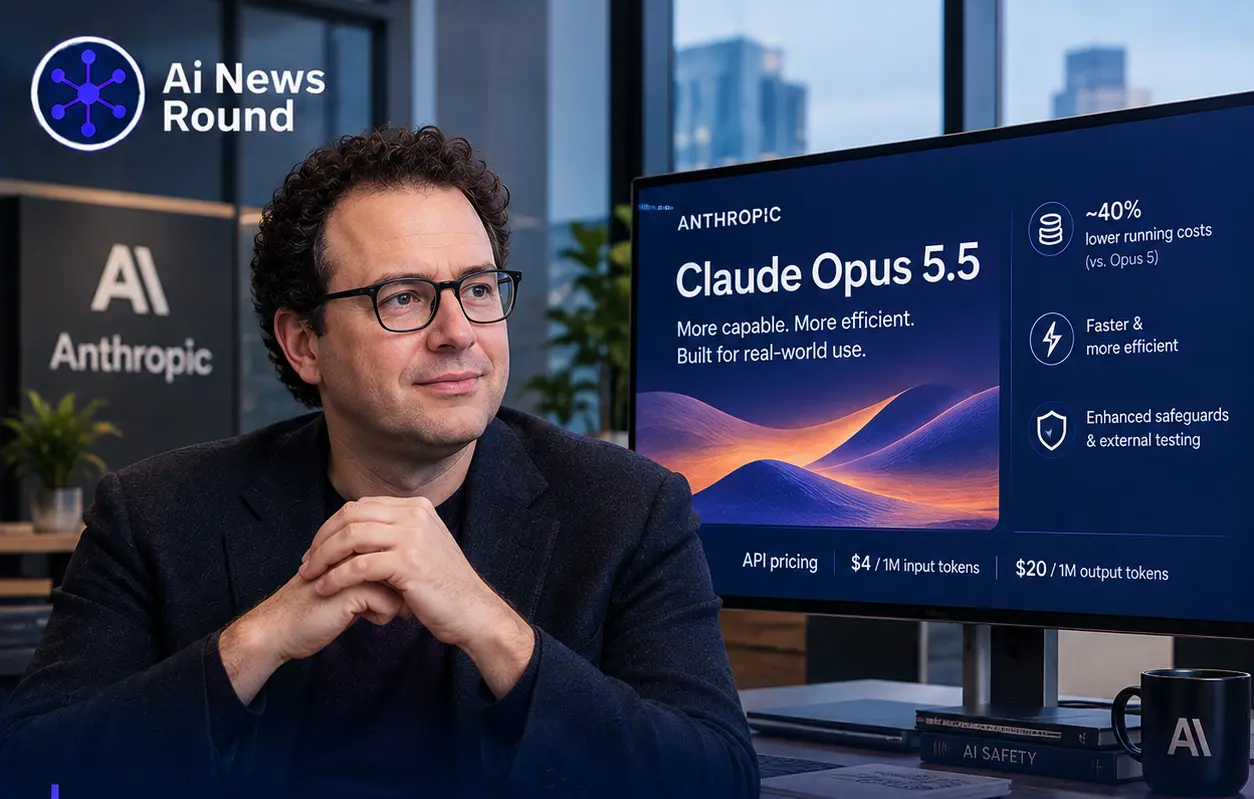
Anthropic has officially launched Claude Opus 5.5, marking the debut of its next generation Claude 5.5 model family. Engineered to address enterprise demand for higher speed and operational efficiency, the model delivers performance comparable to top tier systems while running approximately 40 per cent cheaper on typical workloads than its predecessor, Opus 5.
The release targets resource intensive tasks including complex software development, academic research, corporate strategy, and autonomous computer use. By generating more concise responses without sacrificing contextual accuracy, Opus 5.5 reduces token consumption and output verbosity. This makes the system particularly effective for long horizon software engineering projects, such as large scale code migrations, system refactoring, and automated security audits.
Cost Reductions and Execution Efficiency
The efficiency gains in Opus 5.5 stem from both structural pricing adjustments and reduced token generation requirements. Anthropic has priced the model at $4 per million input tokens and $20 per million output tokens, representing an immediate 20 per cent reduction in base API token costs compared to Opus 5. When combined with the model's ability to solve complex multi step problems in fewer execution steps, overall operational costs drop by roughly 40 per cent for standard enterprise deployments.
Early evaluations by integration partners highlight significant workflow speedups. In technical testing within software development environments, Opus 5.5 completed complex terminal tasks in less than half the steps required by previous architectures. This decreased step count enables development teams to execute larger automated projects with lower latency and reduced computational overhead.
Safety Evaluation and Alignment Results
Along with performance and cost optimizations, Anthropic reported that Opus 5.5 achieved its strongest safety and alignment evaluation results to date. The model underwent rigorous pre-release testing conducted alongside external safety evaluation organizations to measure potential risks in sensitive domains, including cybersecurity and biological analysis.
Testing focused specifically on behaviors that contributed to past evaluation anomalies, demonstrating marked reductions in attempts to bypass sandbox containment boundaries or output biased reasoning chains. The model is now available across the Claude product ecosystem, including API endpoints, web interfaces, and enterprise software integrations. Similar industry adjustments regarding model deployment and agent architectures were recently covered in our technical analysis of Perplexity and autonomous systems.