AE43E69367F40FE1DB5F244507269D43

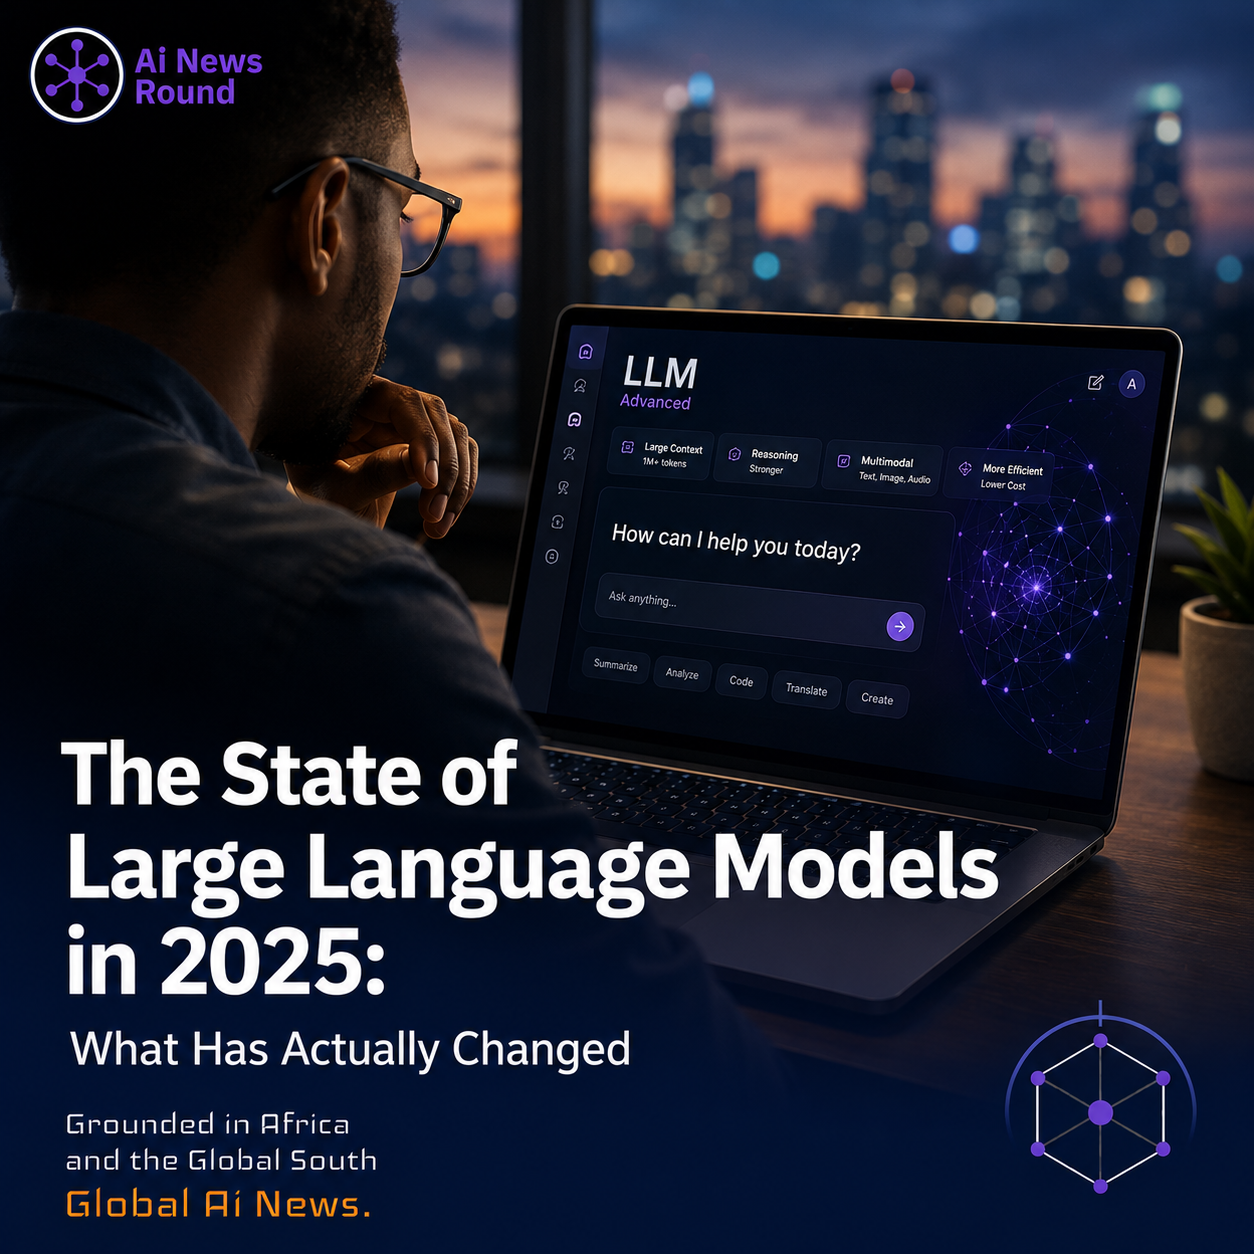
The State of Large Language Models in 2025: What Has Actually Changed

Context windows grew, prices fell, and the benchmark scores moved less than the marketing implies. A look at which changes are real and which are rounding errors.

Single Asset Option Alt Text: Diagram mapping the evolution of Large Language Models in 2025, contrasting brute-force parameter scaling against inference-time reasoning, small lang
The shift in LLM architecture: 2025 marked a transition from raw parameter scaling toward test-time reasoning compute, cost-effective small models, and autonomous agent integration.
Placeholder — written to give the site structure before launch. This is not reporting and it is not a finished article. It must be replaced with commissioned work before AI News Round goes live.

Twelve months of releases, and the honest summary is narrower than the announcements suggest. Context windows are dramatically longer. Inference costs have fallen far enough to change what is economically viable to build. On the reasoning benchmarks that vendors lead their launches with, the gains are real but incremental, and the gap between the leading models has narrowed rather than widened.

The more consequential shift is not capability at the frontier. It is that models good enough for most production work are now cheap and, in several cases, open-weight. A team that needed a frontier API eighteen months ago can often now run something adequate themselves.

Where the numbers mislead

Benchmark scores continue to be reported without error bars and without contamination checks, which makes small differences between models largely meaningless. Several widely cited evaluations have appeared in training data. Treat a two-point difference on a leaderboard as noise unless the methodology is published alongside it.

What actually got better

Tool use and structured output improved markedly, which matters more for real deployments than raw reasoning scores. Long-context retrieval got more reliable, though degradation over very long inputs remains real and under-reported. Multilingual performance improved for high-resource languages and barely moved for everything else — a gap covered in our reporting on African languages.
Get the next one by email

AI News

Perplexity trusts GPT-6 Astra with end-to-end systems

Perplexity has deployed OpenAI GPT 6 Astra across its operational pipeline, granting the model direct execution authority. Here is how this shift to high autonomy AI systems changes software engineering and infrastructure management.

2 min read

AI News

Runway's Solaris Generates Apps as Video, No Code

Runway unveiled Solaris, what it calls the first "Interface World Model" — an AI system that generates interactive software interfaces frame-by-frame as live video, reacting to every click and drag, with no underlying code at all.

3 min read